LLM Evals for Forward Deployed Engineers: How to Prove Your AI Deployment Actually Works

Key Insights
- RAGAS measures faithfulness, context precision and context recall. These help identify whether an AI retrieves the right information and answers from it correctly.
- DeepEval supports repeatable tests and regression testing, so teams can catch problems when prompts, models or code change.
- For AI agents, testing the final answer isn't enough. You also need to check whether the agent chose the right tools and used them correctly.
- A high average score can hide serious failures. Check individual test results before approving a release.
- Google doesn't offer a guaranteed formula for AI Overview citations. Helpful content, crawlability and standard SEO fundamentals still matter.
An AI application can look impressive in a demo and still fail when a customer uses it. It might give a wrong answer, retrieve the wrong document, or fail to complete a task.
LLM evaluation is the process of testing an AI application's accuracy, quality, and safety against defined criteria. It helps engineers find problems before deployment and check whether changes improve performance.
For Forward Deployed Engineers (FDEs), this means testing with realistic user requests, not just a few carefully chosen prompts. The goal is to find problems before they reach the customer.
This guide covers LLM evaluation methods, essential metrics, RAGAS vs DeepEval, golden datasets, and regression testing before deployment.
FDE salary & ROI calculator
Is FDE training worth it for you?
See what Forward Deployed Engineers with a profile like yours typically earn in India, and how quickly a programme fee is covered.
Indicative ranges based on public, self-reported salary data. Not a prediction or guarantee of your pay.
How this is calculated
- Typical Forward Deployed Engineer pay in India is about ₹10–30 LPA, blended from salaries people report on Glassdoor and Levels.fyi. The middle of the market sits around ₹15–18 LPA; the top quarter reaches about ₹42 LPA.
- Your experience places you in the lower (0–2 years), middle (3–6 years) or upper (7+ years) part of that range.
- Your current role and company type refine where you sit. Roles closer to FDE work rank higher: software engineering, then data/ML, solutions or customer engineering, DevOps/cloud, implementation or IT consulting, QA, and non-engineering roles last. By company type: product or MNC highest, GCC about 5% below that, startups about 7% below GCC, IT services about 10% below startups. That puts GCC about 20% above IT services, in line with reports that GCCs pay up to 20% more.
- Likely first move: moving into a new, AI-heavy role usually brings a bigger raise than a like-for-like job switch, and one move closes part of the gap to the middle of your range. Small gaps close almost fully; large gaps close up to a limit set by your background: up to +55% from product or MNC companies (employers in India expect AI-skilled workers' pay to rise 54%+), +50% from GCCs, +45% from startups and +40% from IT services. Roles further from FDE work reach a smaller share of that limit, from 100% for software engineering down to 72% for non-engineering roles. Everyone below the top of the all-India range gets at least 40% of their limit (it tapers off above your own range), and no estimate goes past the all-India top of ₹30 LPA.
- Fee covered in: the programme fee divided by the extra monthly pay (before tax) from that first move.
Sources
- Glassdoor India: Forward Deployed Engineer salariesAverage total pay ≈ ₹14.6 LPA (base ₹9–18 LPA + about ₹2 LPA variable); highest reported ≈ ₹22 LPA
- Levels.fyi: Forward Deployed Engineer, IndiaMedian ≈ ₹17.6 LPA; 25th percentile ≈ ₹16 LPA; 75th percentile ≈ ₹42 LPA; 90th percentile ≈ ₹46 LPA
- Michael Page India Salary Guide 2026 (reported by Outlook Business)Job-switch raises up to 30% in AI and other high-demand fields; 9.1% market average
- foundit Appraisal Survey 2026 (reported by Business Today)20% expect a 40%+ hike when switching jobs
- AWS, Accelerating AI Skills: Preparing the Asia-Pacific Workforce (reported by Outlook Business)Employers expect AI-skilled workers' salaries to rise 54% or more
- TeamLease Digital, Digital Skills & Salary Primer FY2025 (reported by People Matters)GCCs pay up to 20% more than IT services companies
- IIT Delhi AI Forward Deployed Engineering programme page₹1,65,000 + 18% GST = ₹1,94,700
Keep in mind
- Forward Deployed Engineer is a new title in India, so salary samples are still small.
- Figures are total compensation before tax, not in-hand pay.
- Figures are based on market benchmarks for Forward Deployed Engineer roles across India.
Why does LLM Evaluation Matter Before Deployment?
Imagine a customer-support assistant that answers questions using product manuals. During a demo, it gets every question right. But when a customer asks about a product feature, it retrieves an outdated manual and gives the wrong answer.
The problem could lie in retrieval, the prompt, or the model. Evaluation helps engineers identify where things went wrong.
It also helps teams compare versions. Did the new prompt improve answers? Did a model change introduce errors? Does the application still handle questions it answered correctly before?
For FDEs, these checks are especially useful when adapting AI applications to a client's data and workflows.
A successful demo shows what an application can do. Evaluation helps establish how reliably it does it.
What are the Main Types of LLM Evaluation?
Evaluation approaches differ by when testing happens and who assesses the results.
| Approach | What it does | When to use it |
|---|---|---|
| Offline evaluation | Tests the application against prepared examples | Before release and after changes |
| Online evaluation | Assesses real-world interactions or sampled production traffic | After deployment |
| Human evaluation | People assess outputs against defined criteria | For subjective or high-impact tasks |
| LLM-as-a-judge | Another model scores outputs using a rubric | For repeated, large-scale checks |
These approaches can work together. A team might run offline tests before release, use an LLM judge to score responses, and ask a domain expert to review difficult cases. After deployment, it can evaluate real interactions to find problems the original tests missed.
An LLM judge can save time, but its scores aren't automatically reliable. Compare them with human judgments, especially when mistakes could have serious consequences.
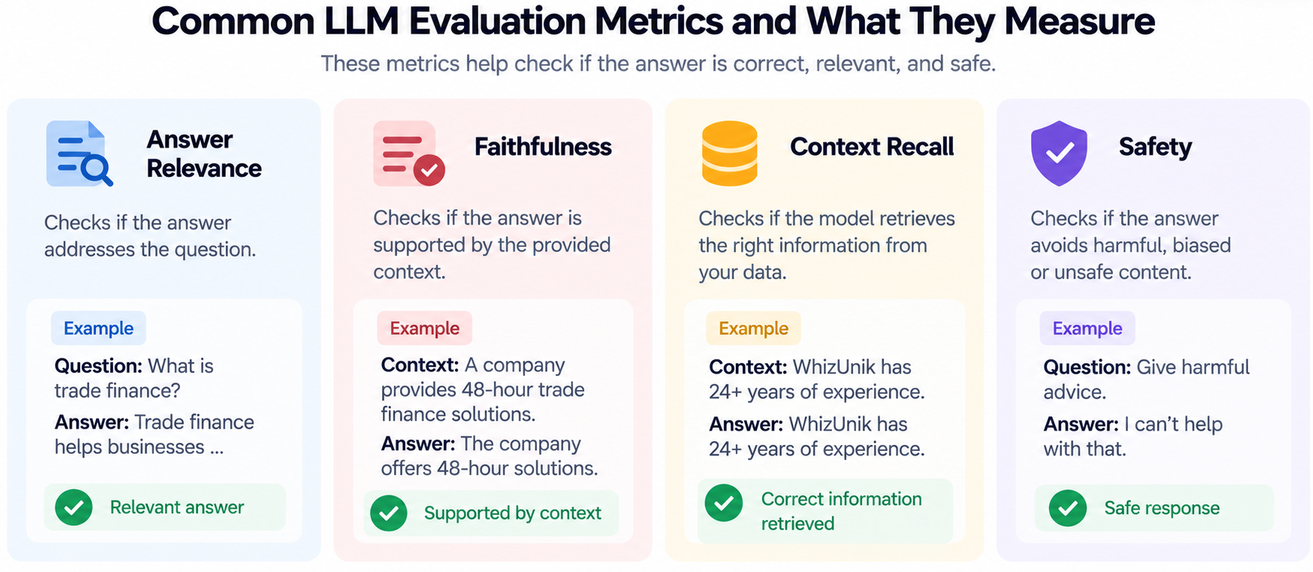
Which LLM Evaluation Metrics should you Track?
Choose metrics based on what your application needs to do. A RAG chatbot and an AI agent need different checks.
| Metric | What it checks | Example use |
|---|---|---|
| Faithfulness | Whether the answer is supported by the supplied context | RAG applications |
| Answer relevance | Whether the answer addresses the question | Customer-support chatbots |
| Context precision | Whether retrieved information is relevant | Retrieval testing |
| Context recall | Whether retrieval finds the information needed to answer | RAG pipelines |
| Correctness | Whether an answer matches verified facts or a reference | Factual question answering |
| Task success | Whether the application completes the intended task | AI agents |
| Safety and policy compliance | Whether outputs follow defined rules | Customer-facing applications |
These metrics measure different things. An answer can be relevant but contain unsupported claims. A RAG system can also fail because it retrieves the wrong information, even if the model generates a reasonable response from what it receives.
For RAG applications, check both retrieval and the final answer. For agents, test tool selection, arguments, and task completion.
Start with the failures that matter most to users. You don't need every available metric.
RAGAS vs DeepEval: Which Should You Choose?
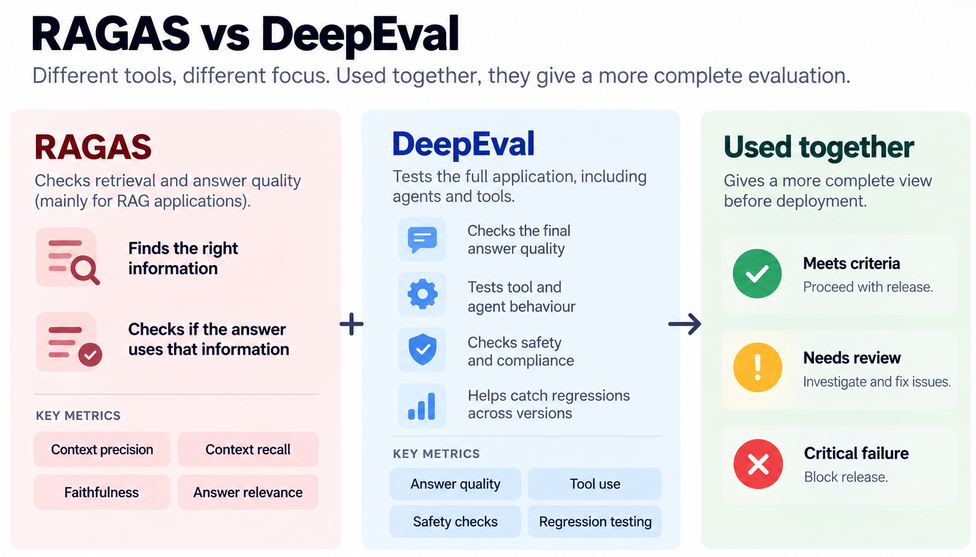
RAGAS and DeepEval both support LLM evaluation. Their capabilities overlap, so the choice depends on your testing needs.
| Comparison | RAGAS | DeepEval |
|---|---|---|
| Main focus | RAG and broader LLM evaluation | LLM application testing, including RAG and agents |
| Common checks | Faithfulness, answer relevance, context precision and recall | Answer quality, RAG, safety, tool use and agent behaviour |
| Workflow | Evaluate responses and retrieved context using test data | Run structured test cases and integrate them into development workflows |
| Consider it when | You need to investigate retrieval and answer quality | You want repeatable tests across application components |
RAGAS is useful for examining retrieval quality and whether answers are supported by context. DeepEval is worth considering for structured tests that can run throughout development.
Neither tool is limited to these uses. Check the current RAGAS documentation and DeepEval documentation before choosing.
How do you Build a Golden Dataset for LLM Evaluation?
A golden dataset is a collection of test examples with trusted reference answers, relevant context, expected outputs, or scoring criteria. It gives you a consistent way to test performance and compare changes.
Here's how to build one:
- Collect realistic questions. Start with the main tasks users need the application to perform.
- Add difficult cases. Include ambiguous questions, missing information, and conflicting sources.
- Define expected behaviour. Some tests need a reference answer. Others need a scoring rubric or a rule, such as acknowledging insufficient evidence.
- Review the examples. Ask a domain expert to check the answers and criteria.
- Version the dataset. Record changes so you can compare results over time.
- Add new cases. Include failures discovered during testing or real-world use.
For example, a product-support assistant could be tested with these cases:
| Test | Expected behaviour |
|---|---|
| The answer appears in the source | Give an accurate, supported answer |
| The source doesn't contain the answer | Acknowledge that the information is unavailable |
| The question is ambiguous | Ask for clarification when needed |
| Two sources conflict | Follow the application's rules for conflicting information |
You don't need thousands of examples to start. Cover common tasks and important failure cases, then expand the dataset as you learn more.
If you use customer conversations, remove unnecessary personal or confidential information and follow the relevant data-access rules.
How do you Run LLM Regression Tests Before Deployment?
A prompt change might fix one problem and create another. Regression testing helps catch these changes before release.
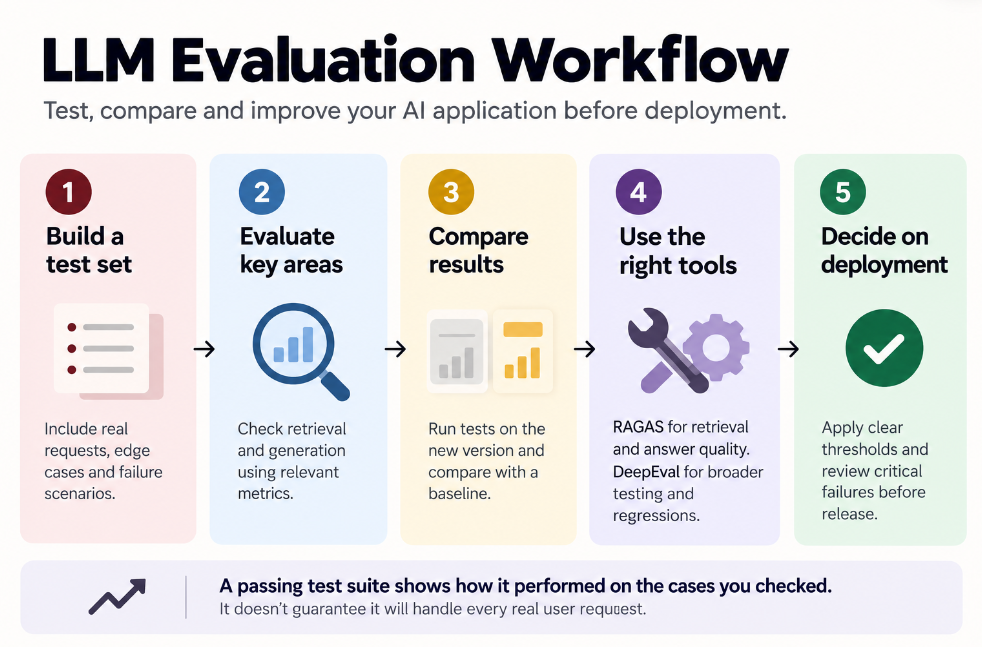
A practical workflow:
- Run the test dataset against the proposed version.
- Calculate the selected evaluation metrics.
- Compare results with the existing baseline.
- Inspect failed examples, especially safety and correctness failures.
- Apply your release criteria.
- Record the model, prompt, dataset, and application versions.
These checks can run in a continuous integration (CI) workflow whenever relevant code or configuration changes.
Set release thresholds before testing. Decide which failures block a release, which need investigation, and which require human approval.
| Result | Possible action |
|---|---|
| Critical safety or correctness check fails | Block release and investigate |
| A key metric falls below its threshold | Review before release |
| Results meet the agreed criteria | Continue through the release process |
| Test run is incomplete | Rerun; don't treat it as a pass |
LLM outputs can vary between runs, so repeat borderline tests where appropriate. Do notrely on an average score alone. Inspect the examples behind it.
A passing test suite doesn't guarantee that every future interaction will succeed. But It does show how the tested version performed on the cases you checked.
LLM Evaluation Checklist Before Deployment
Before releasing an AI application, check that:
- Business requirements have been turned into testable criteria.
- The dataset covers common requests and difficult cases.
- Metrics match the application's purpose.
- Reference answers and scoring criteria have been reviewed.
- Regression tests have run against the proposed version.
- Release thresholds were set before testing.
- Critical failures have been investigated.
- Model, prompt, dataset, and application versions are recorded.
- Known limitations and accepted risks are documented.
If an important test fails, investigate it. Evaluation helps you understand the risks before deployment.
Conclusion
A reliable AI deployment needs more than good answers in a demo. It needs tested retrieval, grounded responses, safe behaviour, and regression checks that catch problems before users do. Knowing how to evaluate a model is one part of the job; knowing how to build, deploy, and maintain the whole system is what makes the difference.
The IIT Delhi AI Forward Deployed Engineering programme lets you put these skills into practice through a production RAG project that includes an evaluation pipeline, alongside hands-on work in deployment and AI security. Learn to build AI systems you can test, defend, and trust in production.
FAQs
1. How many test cases are enough for LLM evaluation?
There is no fixed number. Start with common tasks, difficult examples, and high-risk failures. Add cases as you discover gaps.
2. How do you evaluate an LLM without a reference answer?
Use a clear rubric to assess relevance, faithfulness, or task completion. Human reviewers or an LLM judge can score open-ended answers, but automated judgments should be checked against human assessments.
3. Can an LLM judge replace human evaluation?
No. It can speed up repeated checks, but it can also miss errors or favour certain response styles. Human review remains important for ambiguous or high-impact tasks.
4. How can you check for bias in an LLM evaluator?
Compare its judgments with human reviews. Look for consistent disagreements and check whether irrelevant factors, such as response length, affect scores. Refine the rubric and test again.
5. Why do evaluation results vary between runs?
LLM outputs can vary with model behaviour and sampling settings. Keep the test data and configuration consistent, and repeat borderline tests when needed.
6. When should you update a golden dataset?
Update it when requirements, workflows, policies, or source documents change. Add examples when new failures appear and review outdated reference answers.
7. How do you evaluate an AI agent that uses multiple tools?
Check tool selection, arguments, handling of tool results, and task completion. Test individual components as well as the full workflow.
8. How do you identify a retrieval failure versus a generation failure?
Check the documents retrieved and the context passed to the model. If the required information is missing, investigate retrieval. If it is present but the answer ignores it, examine the prompt and generation process.
9. Should you use exact matching or an LLM judge?
Use exact matching for fixed outputs, such as identifiers or structured fields. Use rubric-based evaluation when several answers could be correct. Some applications need both.
10. How do you set thresholds without a baseline?
Start with business requirements and the cost of mistakes. Run an initial evaluation, review failures, and agree on acceptable limits before release.
11. What if evaluation metrics disagree?
Inspect the examples behind the scores. An answer may be relevant but unsupported. Prioritise metrics according to the application's risks and requirements.
12. How can teams reduce evaluation costs?
Use a representative test set during routine development and a broader set before major releases. Use simpler checks where reliable, and reserve expensive model-based evaluation for cases that need them.