Self-Attention vs Cross-Attention: A Worked Example

Key Insights
- Self-attention allows tokens to exchange information within the same sequence, creating context-aware representations.
- Cross-attention connects two sequences by using queries from one sequence and keys and values from another.
- Both mechanisms use scaled dot-product attention: query-key scores are scaled by the square root of the key dimension, passed through softmax, and used to combine value vectors.
- Multi-head attention runs several attention operations in parallel, allowing Transformers to learn different relationships between tokens.
- Masked self-attention uses a causal attention mask to prevent autoregressive decoders from accessing future positions during generation.
- In encoder-decoder Transformers, cross-attention allows decoder states to retrieve relevant information from encoder outputs; related mechanisms can also connect modalities in multimodal models.
- The attention score matrix has dimensions
 for self-attention and
 for cross-attention, where
 and
 are the query and key sequence lengths.
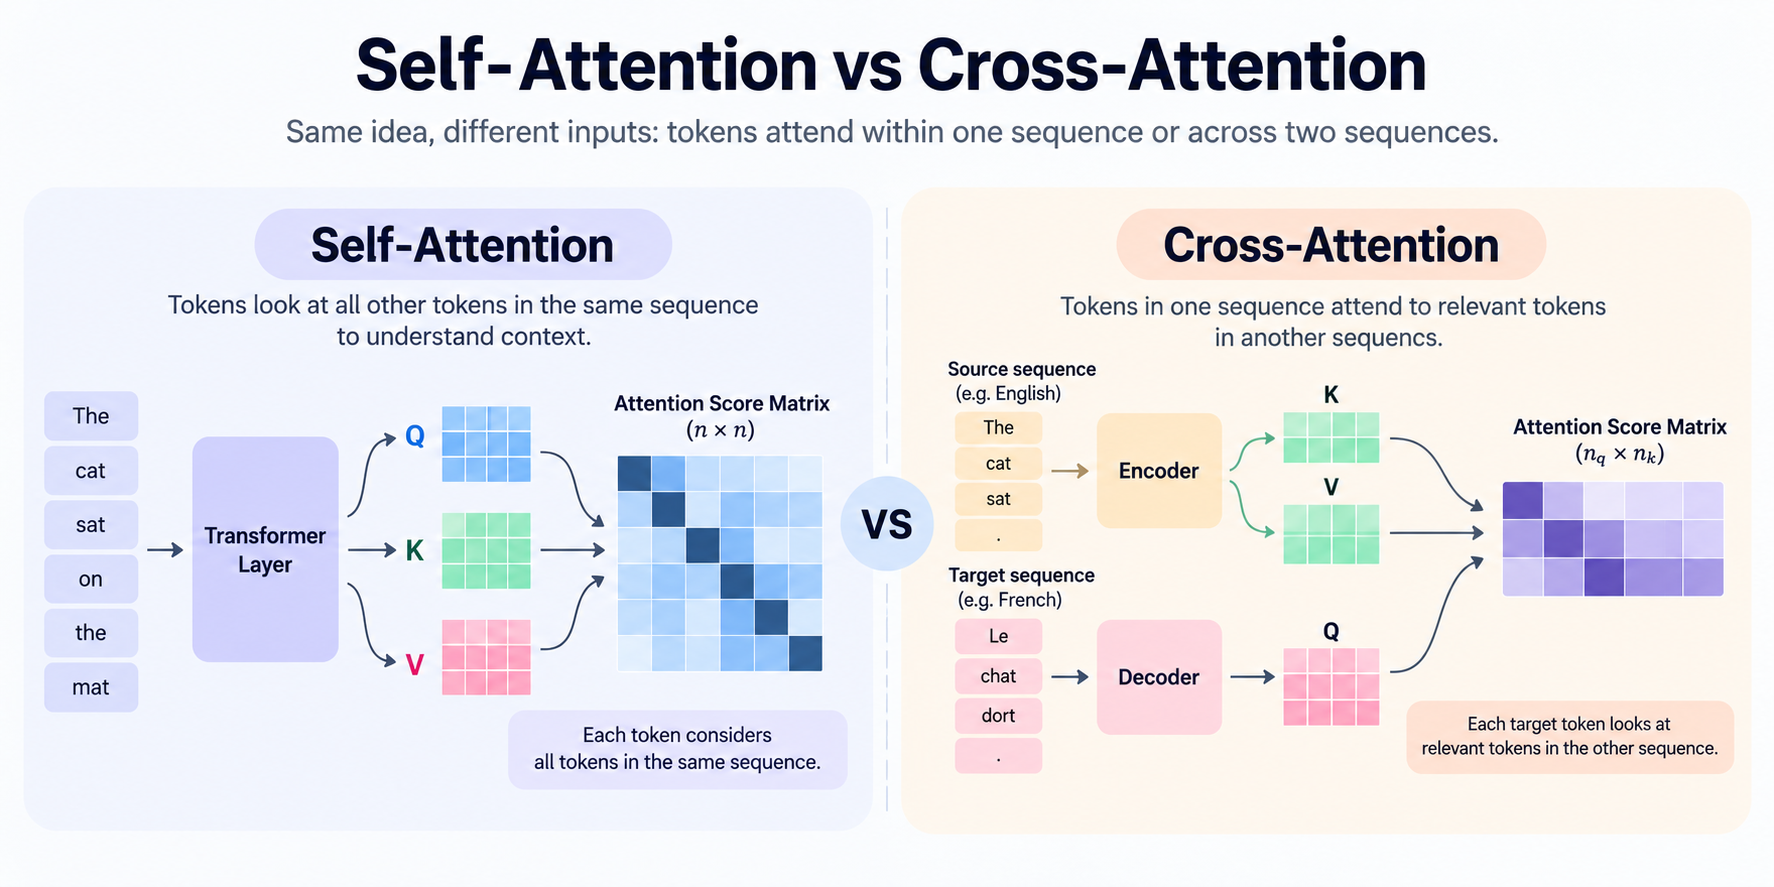
Self-attention is a neural network mechanism that allows every token in a sequence to attend to other tokens in the same sequence to understand their meaning and context. Cross-attention, in contrast, allows tokens in one sequence to retrieve relevant information from another. Both use queries (Q), keys (K) and values (V), but the key difference lies in where these vectors originate.
Understanding the self-attention vs cross-attention difference is essential to understanding how Transformers build contextual representations and connect information across sequences. This guide walks through a worked numerical example of the self-attention mechanism, applies the same calculation to cross-attention, and compares their inputs, calculations and practical uses.
Why is Attention Needed in Transformers?
Attention enables a Transformer to determine which tokens are relevant to a particular token and combine their information into context-aware representations.
How does attention connect related tokens?
Consider the sentence: “The animal was tired because it ran.”
To interpret “it,” a model needs information about the earlier words, particularly “animal.” Attention allows a token’s representation to incorporate information from other relevant positions rather than processing every token independently.
Boundary: Self-attention creates these connections within a sequence. The following calculations show how it works.
How does Self-Attention Work Step by Step?
The self-attention mechanism projects the same input sequence into Q, K and V matrices. It calculates query-key similarity scores, applies softmax to obtain attention weights, and uses those weights to combine value vectors.
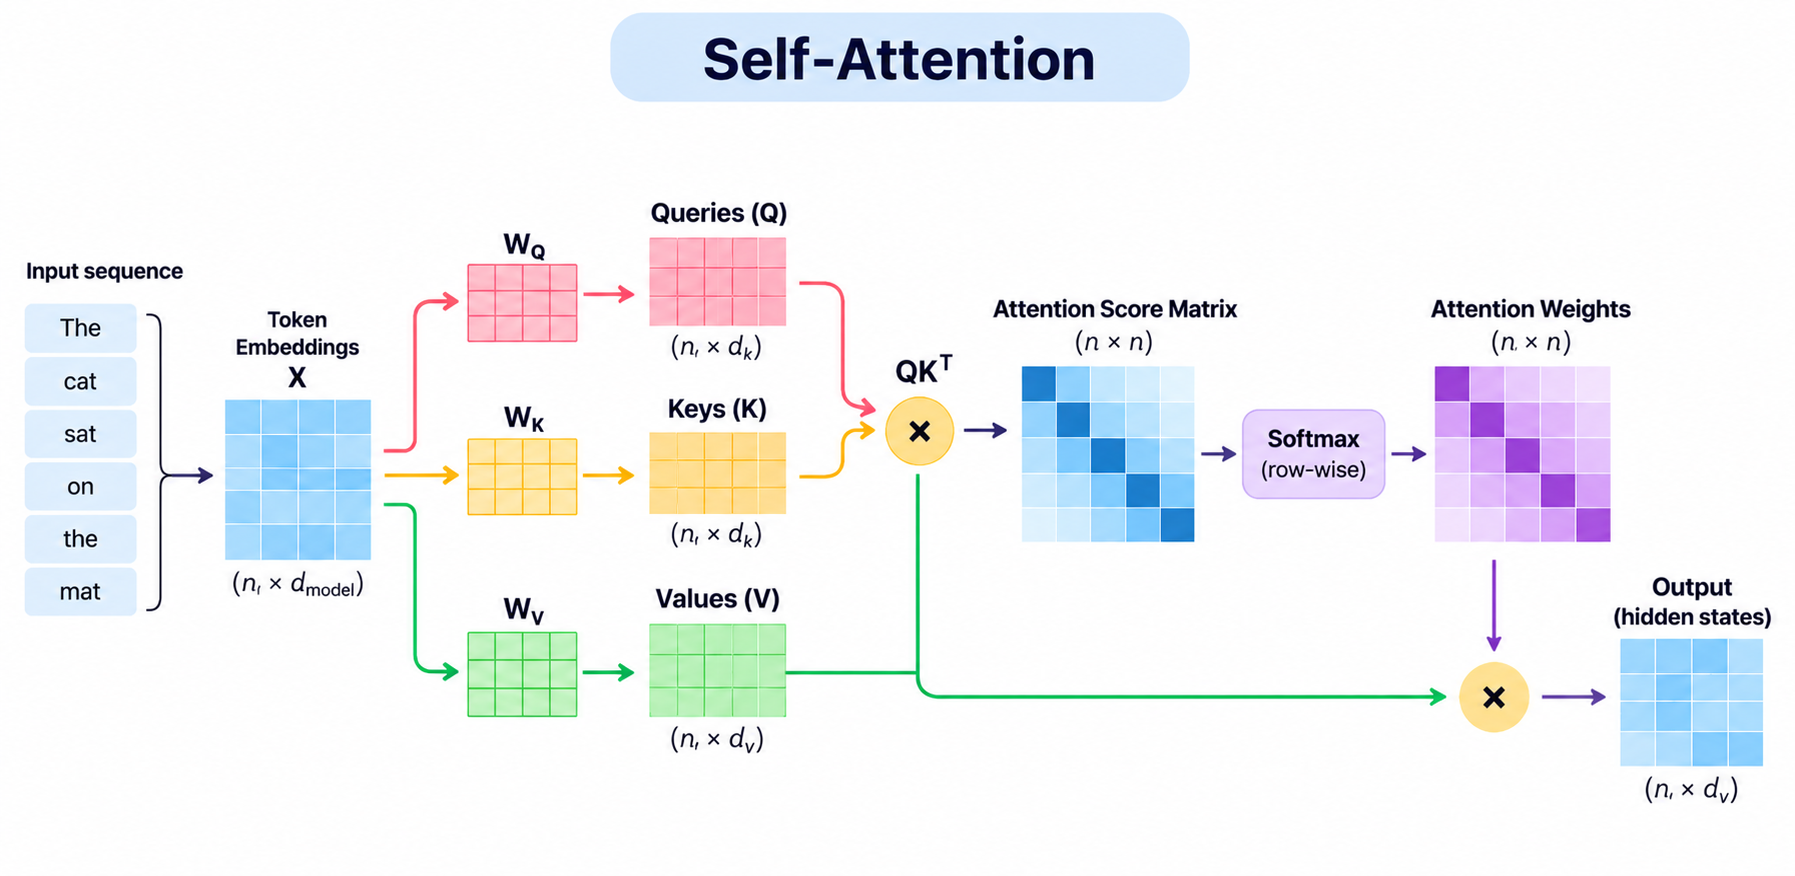
What do queries, keys and values represent?
- Query (Q): Represents what a token is looking for.
- Key (K): Represents the features used to match a token against a query.
- Value (V): Contains the information combined to produce the output.
The projections are:
Q = XWQ
K = XWK
V = XWV
Here, X represents the input token representations, while WQ, WK and WV are learned projection matrices.
Worked example: Calculate self-attention using small matrices
Consider a two-token sequence with the following deliberately simplified matrices:
Q = K=[[1, 0], [0, 1]]
V = [[1, 0], [0, 2]]
These matrices are illustrative; they are not trained model parameters.
Step 1: Calculate the raw attention scores.
Multiply Q by the transpose of K:
QKᵀ = [[1, 0], [0, 1]]
Each token has a score of 1 for itself and 0 for the other token.
Step 2: Apply scaled dot-product attention.
The self-attention formula is:
Attention(Q, K, V) = softmax(QKᵀ / √dk)V
Here, dk is the key-vector dimension, which is 2. Divide the scores by √2:
QKᵀ / √2 ≈ [[0.707, 0], [0, 0.707]]
Scaling helps prevent large dot products from producing excessively concentrated softmax distributions.
Step 3: Apply row-wise softmax.
Softmax converts each row of scores into weights that sum to 1:
Attention weights ≈ [[0.67, 0.33], [0.33, 0.67]]
These rounded values indicate how much each token attends to both positions.
Step 4: Multiply the weights by V.
[[0.67, 0.33], [0.33, 0.67]] × [[1, 0], [0, 2]]
Output ≈ [[0.67, 0.66], [0.33, 1.34]]
Each output combines information from both value vectors. The first token assigns more weight to the first value, while the second assigns more weight to the second.
Why is the score divided by the square root of the key dimension?
As the key dimension increases, dot products can become large in magnitude. Large scores can make softmax distributions overly concentrated and produce small gradients. Dividing by √dk helps control their scale during training.
Boundary: This example demonstrates one attention head. Transformers can use multiple heads and masks to capture different relationships or restrict which tokens can interact.
What are Multi-Head Attention and Masked Self-Attention?
Multi-head attention runs multiple attention operations in parallel, while masked self-attention restricts which positions a token can access.
How does multi-head attention work?
Each head uses its own learned Q, K and V projections. Different heads can learn different relationships, such as nearby dependencies or longer-range contextual links. Their outputs are concatenated and passed through an output projection.
However, individual heads are not guaranteed to specialise in a particular relationship; their behaviour depends on what the model learns.
What does a causal mask do?
A causal attention mask prevents a token from attending to future positions. For three tokens, the allowed positions can be represented as:
[[1, 0, 0],
[1, 1, 0],
[1, 1, 1]]
Here, 1 means attention is allowed and 0 means it is blocked. In implementations, blocked scores are typically masked before softmax.
Masked self-attention is used in autoregressive decoders, including GPT-style models, so predictions do not use future tokens that would be unavailable during generation.
Boundary: Masking changes which positions can contribute, not where Q, K and V originate. Cross-attention changes that source.
How does Cross-Attention Work?
Cross-attention uses queries from one sequence and keys and values from another. In a standard encoder-decoder Transformer, decoder states provide Q, while encoder outputs provide K and V.
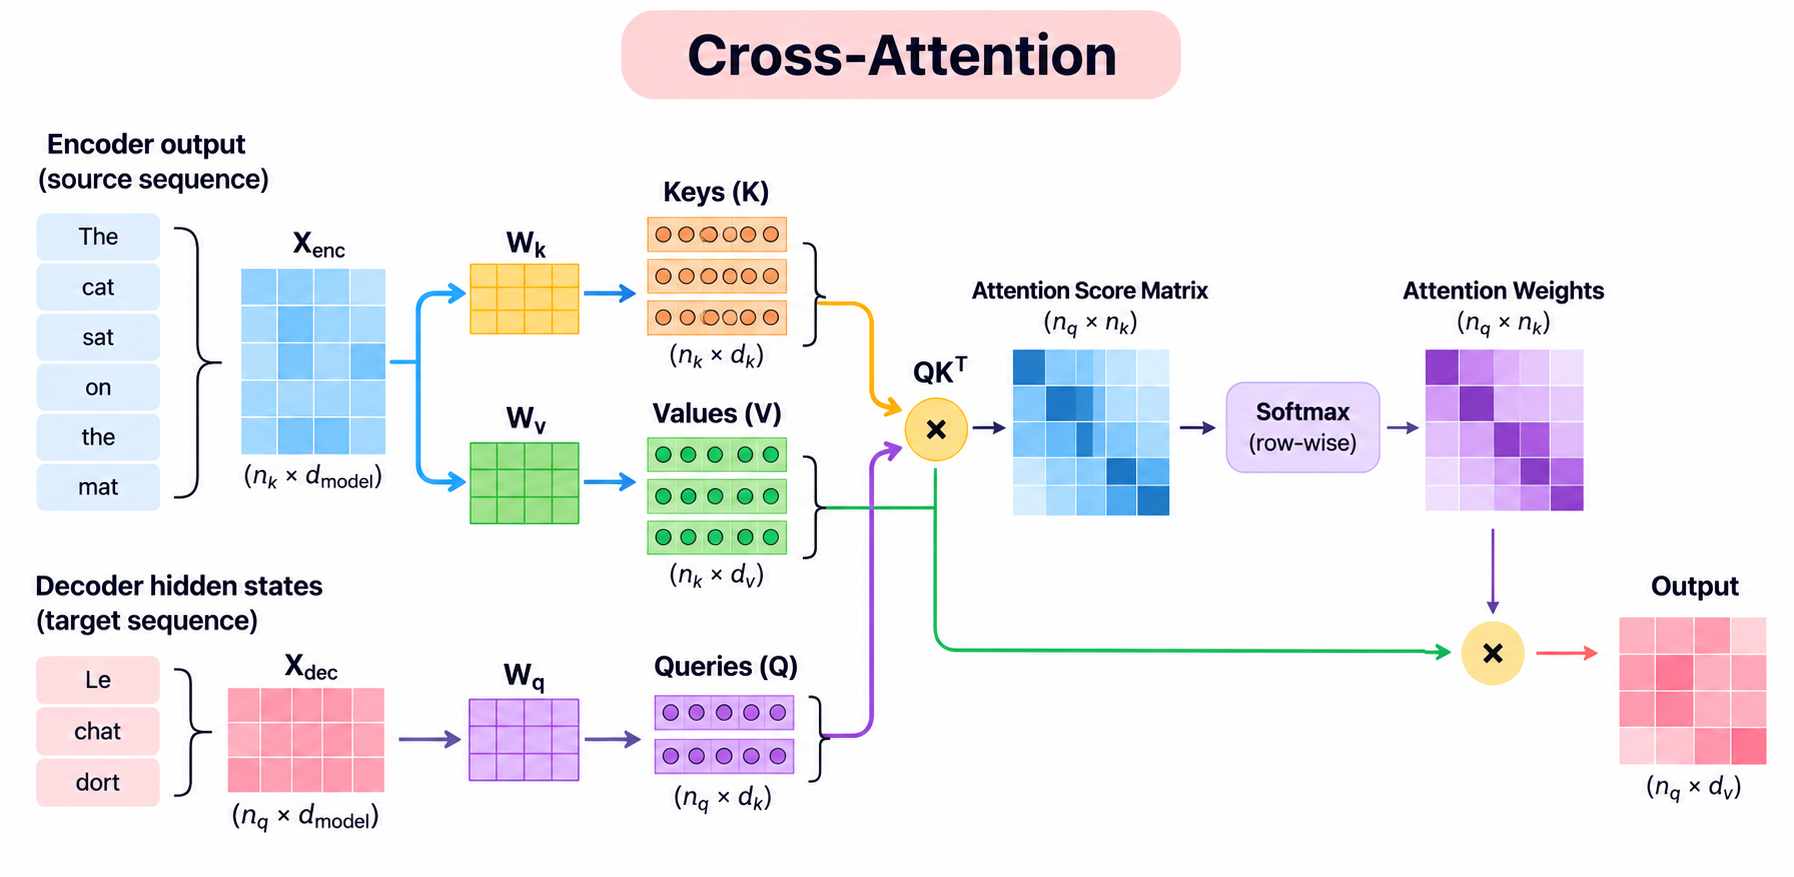
How does cross-attention work in an encoder-decoder Transformer?
In machine translation, the encoder processes a source sentence, such as “The cat sleeps.” The decoder generates the target-language sentence while accessing relevant information from the encoded source.
The projections are:
Q = XdecoderWQ
K = XencoderWK
V = XencoderWV
The same scaled dot-product attention formula applies. The key difference is that the query and key-value matrices come from different sequences.
A small cross-attention example
Consider one decoder query and two encoder positions:
Q = [[1, 0]]
K = [[1, 0], [0, 1]]
V = [[2, 0], [0, 4]]
Step 1: Calculate and scale the scores.
QKᵀ = [[1, 0]]
Since dk = 2:
QKᵀ / √2 ≈ [[0.707, 0]]
Step 2: Apply softmax.
Attention weights ≈ [[0.67, 0.33]]
Step 3: Multiply by V.
[[0.67, 0.33]] × [[2, 0], [0, 4]]
Output ≈ [[1.34, 1.32]]
The decoder query assigns more weight to the first encoder position, while still incorporating information from the second. All decimal values in these examples are rounded approximations.
Where is cross-attention used beyond translation?
Cross-attention is used in encoder-decoder tasks such as translation and summarisation. It can also connect different modalities in multimodal models, such as allowing text representations to attend to image features. The exact design varies, and not every multimodal architecture uses cross-attention in the same way.
Boundary: Both mechanisms use the same core calculation. Their difference lies in how the input representations are connected.
Self-Attention vs Cross-Attention: What Is the Difference?
The main self-attention vs cross-attention difference is the origin of Q, K and V. Self-attention derives all three from the same sequence, while cross-attention uses Q from one sequence and K and V from another.
| Feature | Self-attention | Cross-attention |
|---|---|---|
| Input source | One sequence | Two sequences or representations |
| Query (Q) | Same sequence as K and V | Querying sequence |
| Keys (K) and values (V) | Same sequence as Q | Separate sequence |
| Main purpose | Build context within a sequence | Transfer information across sequences |
| Typical use | Encoder attention; decoder masked attention | Encoder-decoder attention |
| Attention score matrix | Input length × input length | Query length × key/value length |
| Example | Connecting words in a sentence | Decoder attending to source tokens |
How can you identify which type of attention a model uses?
Check where Q, K and V originate. If all three come from the same sequence, it is self-attention. If Q comes from one sequence and K and V from another, it is cross-attention.
A causal mask does not turn self-attention into cross-attention. It simply restricts which positions within the same sequence can contribute.
Boundary: These distinctions provide a practical way to recognise attention operations when studying Transformer architectures or reading their implementations.
Conclusion
Self-attention builds contextual relationships within a sequence, whereas cross-attention allows one sequence to retrieve information from another. Both rely on Q/K/V projections, scaled dot-product attention and softmax, but differ in their input sources and typical uses. Working through the attention score matrix and output calculation makes this distinction easier to understand.
To explore these concepts alongside Transformer architecture and other Generative AI foundations, explore the Generative AI programme by IIT Delhi, delivered on Varsity by InterviewBit.
Frequently Asked Questions
Can self-attention and cross-attention use the same attention formula?
Yes. Both can use scaled dot-product attention. The difference is whether Q, K and V originate from one sequence or from separate sequences.
Does cross-attention always require an encoder-decoder architecture?
No. Encoder-decoder Transformers are a common example, but cross-attention can also connect different modalities or representations.
Can the query and key/value sequences have different lengths?
Yes. The output has one row per query position, while the attention score matrix has one column per key position.
Why do attention weights add up to one?
Softmax normalises the scores across the available positions for each query, so the weights sum to one, subject to numerical rounding.
Does self-attention preserve the original token embeddings?
Not necessarily. It produces context-enriched representations by combining value vectors according to the attention weights.
Is masked self-attention the same as cross-attention?
No. Masked self-attention restricts access to positions within a sequence. Cross-attention connects queries from one sequence to keys and values from another.
What happens if all attention scores are equal?
Softmax assigns equal weights to all unmasked positions. The output becomes the average of their value vectors.
Does every Transformer layer contain cross-attention?
No. Encoder-only and decoder-only Transformers can use self-attention without a separate cross-attention layer. Standard encoder-decoder Transformers typically include cross-attention in the decoder.
How does sequence length affect the attention matrix?
For self-attention with sequence length n, the score matrix contains n × n entries. For cross-attention, it contains nq × nk entries, where nq is the query length and nk is the key/value length.
What should I calculate first when solving an attention problem by hand?
Identify the origins and dimensions of Q, K and V. Then calculate QKᵀ, scale the scores, apply softmax row-wise, and multiply the resulting weights by V.